Articles
42 articles
No articles match these filters. Try fewer keywords or use All articles / reset.
Use blob leases to build a reusable, globally coordinated job lock for data engineering workloads.
Learn how Fabric Spark Runtime 2.0 incrementally clusters Delta tables, limits write amplification, and maintains file-skipping quality.
Most Spark developers learn to write data with df.write long before they ever encounter df.writeTo. It is simple, familiar, and everywhere: choose a format, pick a mode, add a few options, and save the result to a table or path. For years, that mental model worked well enough. Spark was often writing files first and tables second.
Schema inference is convenient. In production or benchmarking, it is often a silent performance killer.
Coming from a notebook-first Spark background, I wanted to write the introduction to Spark Job Definitions (SJDs) that I wish I had when I first encountered them. If you are first interest in why you might want to use a Spark Job Definition over a Notebook, see my blog here.
I’m guilty. I’ve peddled the #NotebookEverything tagline more than a few times.
I’m excited to formally announce LakeBench, now in version v0.3, the first Python-based multi-modal benchmarking library that supports multiple data processing engines on multiple benchmarks. You can find it on GitHub and PyPi.
Last December (2024) I published a blog seeking to explore the question of whether data engineers in Microsoft Fabric should ditch Spark for DuckDb or Polars. Six months have passed and all engines have gotten more mature. Where do things stand? Is it finally time to ditch Spark? Let The Small Data Showdown ‘25 begin!
This is part 2 of my prior post that continues where I left off. I previously showed how you can use Resource folders in either the Notebook or Environment in Microsoft Fabric to do some pretty agile development of Python modules/libraries.
If there anything that data engineers agree about, it’s that table compaction is important. Often one of the first big lessons that folks will learn early on is that not compacting tables can present serious performance issues: you’ve gotten your lakehouse pilot approved and it’s been running for a couple months in production and you find that both reads and writes are increasingly getting slower and slower while your data volumes have not increased drastically. Guess what, you almost surely have a “small file problem”.
I’ve previously blogged in detail about V-Order optimization. In this post, I want to revisit the topic and demonstrate how V-Order can be strategically enabled in a programmatic fashion.
With Spark and Delta Lake, just like with Hudi and Iceberg, there are several ways to enable or disable settings that impact how tables are created. These settings may affect data layout or table format features, but it can be confusing to understand why different methods exist, when each should be used, and how property inheritance works.
There’s been a lot of excitement lately about single-machine compute engines like DuckDB and Polars. With the recent release of pure Python Notebooks in Microsoft Fabric, the excitement about these lightweight native engines has risen to a new high. Out with Spark and in with the new and cool animal-themed engines— is it time to finally migrate your small and medium workloads off of Spark?
I’m thrilled to announce that my Microsoft Fabric Shape Library for Excalidraw has been published!
Since Delta 2.3, deletion vectors have been available, but only recently have we been able to take full advantage of them to improve the performance of write operations. As of Delta 3.1, all operations support deletion vector optimizations. Fabric customers using Runtime 1.3 (Delta 3.2) can now benefit from much faster writes with very little impact on reads.
I frequently hear people talk about Spark as being this complex, pro-dev oriented engine, that is unapproachable to the traditional SQL developer and modern Analytics Engineer. Commonly referenced is the necessity to learn Python, Scala, and completely different data processing constructs.
In any programming environment, handling unreliable processes—whether due to API rate limiting, network instability, or transient failures—can be a significant challenge. This is not exclusive to Spark but applies to distributed systems and programming languages across the board. In this post, we’ll focus on Python (since I’m a PySpark developer) and explore how to make any unstable process more resilient by leveraging the open-source library Tenacity. By adding strategic retry logic with exponential backoff, we can gracefully handle API throttling, server-side failures, and network interruptions to build more robust and fault tolerant solutions.
Spark is fantastic for distributed computing, but can it help with tasks that are not distributed in nature? Reading from a Delta table or similar is simple—Spark’s APIs natively parallelize these types of tasks. But what about user-defined tasks that aren’t inherently distributed?
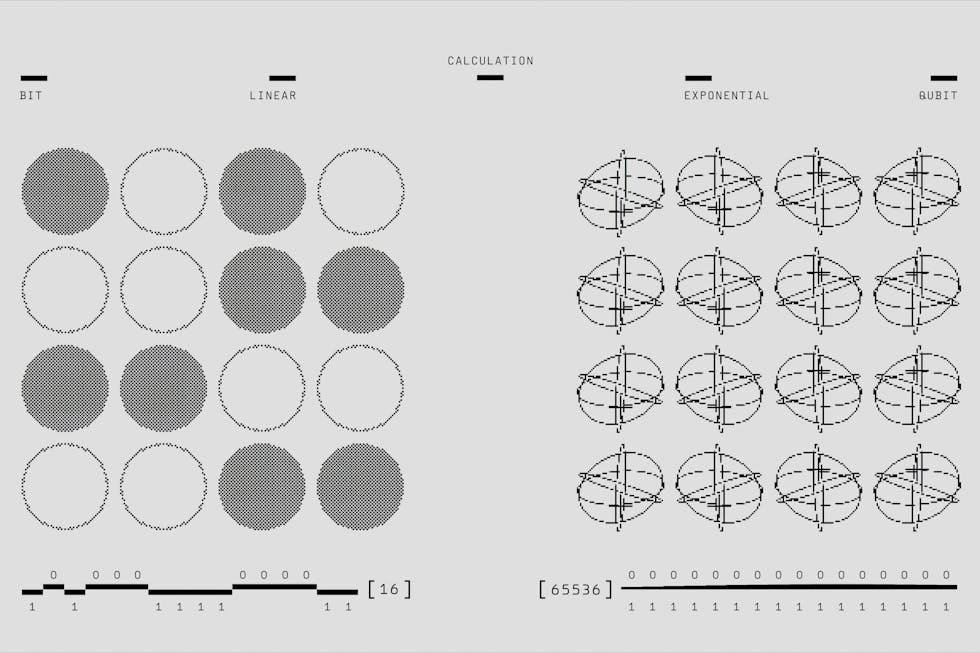
I was 95% done with writing a fun case study on how to parallelize API calls and other non-distributed tasks in Spark when I realized that I was about to gloss over a extremely foundational topic in Spark: RDDs. While most developers minimally understand the basics of DataFrames, RDDs are less commonly known, partly because they are a lower-level abstraction in Spark and DataFrames are full featured enough that you can often get away without needing to know what an RDD is.
Options, options, options. There are now plenty of documented ways to connect from a Spark (or soon Python) notebook to run Data Query Language (DQL) or Data Manipulation Language (DML) commands on top of the SQL Endpoint or Fabric Warehouse. Sandeep has already done a recap of these options in his blog, and Bob Duffy explores another method, using PyOdbc + SqlAlchemy in his post. While each method has pros and cons, I wanted to jump in with yet another way to connect, one I believe is the simplest and most streamlined method available in Python.
In the Fabric Spark environment used for this September 2024 article, V-Order was enabled by default as a Spark configuration. V-Order is a Parquet write optimization that seeks to logically organize data based on the same storage algorithm used in Power BI’s VertiPaq engine.
One of the most critical challenges in large-scale data processing with Apache Spark is tracking what each job is doing. As Spark applications grow in complexity, understanding what’s running and when can become difficult, especially when looking at the Spark UI.
Every software platform has its own terminology, and when terms overlap but don’t mean the same thing, it can be quite confusing. For example, coming from my years as a developer in Databricks land, I initially assumed that Fabric Spark Pools were just like Pools in Databricks. However, as I discovered, this assumption was completely wrong—and understanding this distinction is key to designing the right architecture.
At the time of writing this post, Fabric Spark Runtimes enable Optimized Write by default as a Spark configuration setting. This Delta feature aims to improve read performance by providing optimal file sizes. That said, what is the performance impact of this default setting, and are there scenarios where it should be disabled?
How do you develop a python library in Microsoft Fabric while maintaining the full ability to test code prior to packaging?
With Microsoft Build 2024 underway, the wave of announcements are hot off the press! This is a recap of some of the data engineering specific updates that I’m particularly excited about.
LLMs like ChatGPT and CoPilot are transforming every industry, so why not use them as a data engineer to free up time for more complex tasks? One thing every data engineer—and most humans—are revolted by is repetitive tasks. Thankfully, we don’t live in the world of iRobot and all we need are tokens to pay the LLM masters to get our work done.
I recently blogged about cluster configuration options in Spark and how you can maximize compute utilization and processing time. Of the many options that I listed and data provided, I never gave any benchmarks comparing RunMultiple and Multithreading. The goal of this post is exactly that, drilling into real data that pushes the concurrency limits of both. Going forward I’ll reference Multithreading simply as ThreadPools since that is the specific Multithreading implementation that I’ll be testing.
I’ve had a draft blog post labeled Are Azure Synapse Dedicated Pools Dead that I’ve periodically added thoughts to for the last year but haven’t pulled the trigger on publishing.
So, pretty much everyone seems to be on board with Lakehouse architecture these days, and for good reason. Decoupled compute and storage with all of the best data warehousing type features and more via Delta Lake is a pretty easy sell. It’s a complete no-brainer for greenfield development, but the conversation gets quite a bit more nuanced as you start talking about migrating, or more accurately, replatforming from a traditional data warehousing platform (coupled compute and storage) to Lakehouse.
With Microsoft going all in on Delta Lake, the landscape data architects deeply integrated with the Microsoft stack is undergoing a significant transformation. The introduction of Fabric and OneLake with a Delta Lake driven architecture meanas that the decision on which data platform to use no longer hinges on the time and complexity of moving data into the platform’s data store. Instead, we can now virtualize our data where it sits, enabling various Delta-centric compute workloads, including Power BI.
Have you ever needed to delve into the Information Schema within a notebook environment? There are myriad reasons for wanting to do so, such as: Programmatically recreating view definitions in another lakehouse Identifying table dependencies via view definitions Locating tables that include a soon-to-be-dropped column
Something I’ve always found challenging in PaaS Spark platforms, such as Databricks and Microsoft Fabric, is efficiently leveraging compute resources to maximize parallel job execution while minimizing platform costs. It’s straightforward to spin up a cluster and run a single job, but what’s the optimal approach when you need to run hundreds of jobs simultaneously? Should you use one large high-concurrency cluster, or a separate job cluster for each task?
Unity Catalog introduces many new concepts in Databricks, particularly around security and governance. One significantly improved security feature that Unity Catalog enables is Row Level Security (hereby referred to as RLS).
Apache Spark offers tremendous capability, regardless of the implementation—be it Microsoft Fabric or Databricks. However, with vast capabilities comes the risk of using the wrong “tool in the shed” and encountering unnecessary performance issues.
TL;DR For developers, Chocolatey is an essential tool to address the challenges of installing and managing software.
Ever wished you could add dynamic content, parameterize, or reference a Key Vault secret value for Linked Service properties that only accept static inputs in the Azure Data Factory or Azure Synapse UI? In this post, I’ll introduce you to a feature that’s often overlooked, but incredibly handy for these purposes.
Since its introduction, Unity Catalog has been creating significant buzz in the data community. But what exactly is it, and why is enabling it in your Databricks workspace so important? This article dives into the essence of Unity Catalog, demonstrating how it revolutionizes data engineering in lakehouses and provides guidelines for enabling it in your existing Databricks Workspace.
So you’ve figured out how to write data into Delta format, congratulations! You’ve joined the Delta Lake club and are enabled for all the goodness that comes with Detla, such as ACID transactions, time travel, etc. Now, how do you ensure that the underlying storage of your Delta Tables is maintained so that as you have inserts, updates, and deletes taking place over time, your data is still stored in the most optimal manner.
Data engineers and architects will often spend many hundreds of hours building a complex and fully automated solution for delivering data analysis capabilities to end users but will often forget or overlook the step of provisioning user access to said capabilities. Database logins, users, and role memberships are traditionally created manually in each environment for several reasons, in this article I’ll challenge this status quo and propose that user provisioning may be better suited to be managed via Azure Active Directory security groups. This works with Azure Synapse (Dedicated and Serverless), SQL Database, SQL Managed Instance, other Microsoft SQL variants, and all surrounding cloud services (i.e. data lake, Synapse Workspace, etc.).
Proper use of table distributions in Synapse Dedicated SQL Pools is easily the #1 shortcoming in Synapse implementations.